
By Gabby J ·
How to Build an AI Chatbot for a Website Using RAG
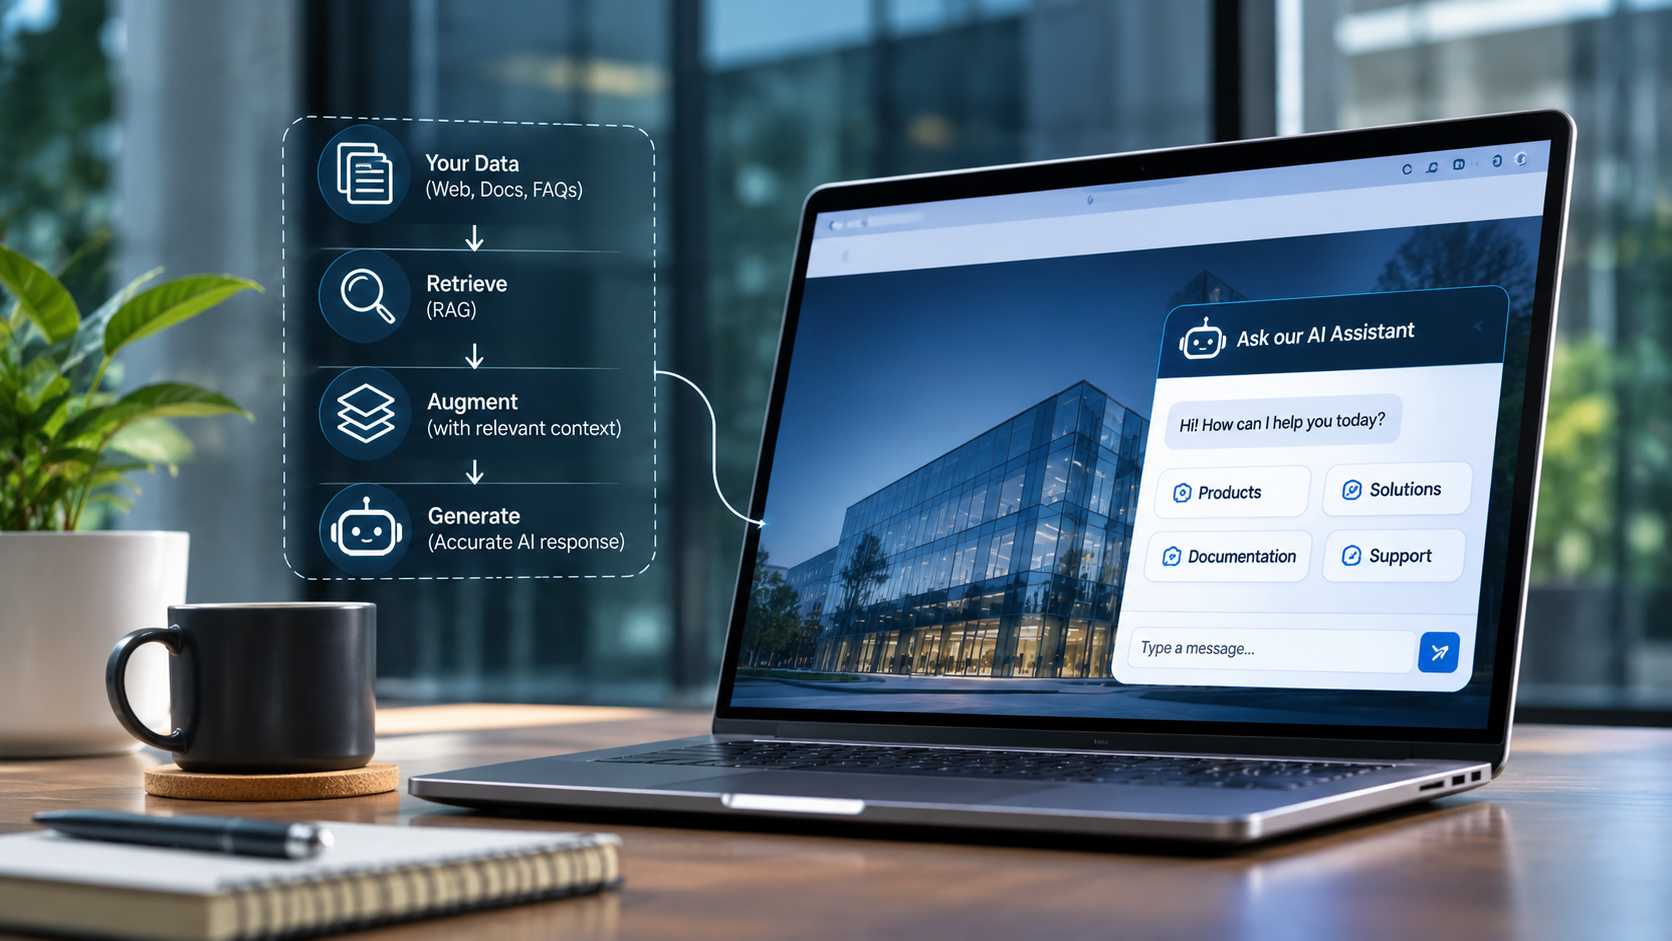
Building the Emkionyx website chatbot, exploring the technical approach behind RAG, intelligent information retrieval and creating a more engaging AI-powered experience.
Introduction: Remember Clippy?

If you've used Microsoft Office in the past, you probably remember Clippy, the animated paperclip that would appear on your screen offering help. Then there was Merlin, the wizard, and Rover, the little dog from Windows XP's Search Companion. They were simple, sometimes amusing and occasionally a little too eager to help. But they introduced an interesting idea: what if software could assist users through a more natural, conversational experience?
AI has taken that idea much further. Today's assistants can understand questions expressed in natural language, search through large collections of information and generate responses based on what they find.
I wanted to bring that experience to Emkionyx.com by building a chatbot that could help visitors explore the company's products, solutions, services and other information without having to navigate through multiple pages. It needed to do more than respond to predefined questions. It had to understand what visitors were asking, identify relevant information from the website and use that information to construct useful answers.
For this, I chose Retrieval-Augmented Generation (RAG). The idea was to build an assistant around Emkionyx's own website content, rather than rely entirely on a general-purpose language model.
The interesting part was that the project involved much more than connecting an AI model to a chat interface. It required a complete pipeline for preparing website content, retrieving relevant information, generating responses, controlling unrelated queries and keeping the knowledge base updated. And eventually, the chatbot got a personality of its own, especially when it transformed into Emkioween for Halloween.
Why I Chose RAG for the Website Chatbot ?
A general-purpose language model can answer a wide variety of questions, but it doesn't automatically know the specific details of a company's products, services or solutions. Even when it generates a convincing response, there is no guarantee that the information accurately reflects what the company actually offers.
A conventional chatbot presents a different challenge. Its responses are usually based on predefined questions, keywords or conversation flows. This can work for simple interactions, but it becomes restrictive when visitors ask questions in different ways or want information that isn't covered by a predefined response.
I needed something that combined the flexibility of natural-language interaction with the reliability of retrieving information from a specific knowledge source.
That is where RAG becomes useful.
Retrieval-Augmented Generation works by retrieving relevant information from an external knowledge base before passing it to a language model. The model then uses that information as context when generating its response.
The process has three main stages:
- Retrieval: Find information relevant to the visitor's question from the knowledge base.
- Augmentation: Supply the retrieved information to the language model as context.
- Generation: Generate a natural-language response using that context.
For the Emkionyx chatbot, the website CMS served as the primary source of knowledge. This allowed the assistant to answer questions using the company's own published information, including product details, solution descriptions, services, company information and FAQs.
However, having the right knowledge source was only the beginning. The next challenge was turning that content into something the retrieval system could search efficiently.
Designing the Architecture
I wanted the chatbot to operate without maintaining separate application servers for its different components. Request handling, embedding generation, information retrieval and response generation needed to work together as one system.
I built the chatbot using a serverless edge architecture, with Cloudflare providing the infrastructure for compute, AI inference, vector storage and database operations.
The architecture has four main responsibilities:
- Request handling: Receives visitor questions and coordinates the chatbot workflow.
- AI processing: Generates embeddings and produces responses using a language model.
- Knowledge retrieval: Searches the stored website content using semantic and keyword-based approaches.
- Content management: Keeps the chatbot's knowledge base synchronised with changes in the CMS.
Rather than treating these as independent operations, I designed them to work together through a single request and retrieval pipeline.
When a visitor submits a question, the request is processed by the backend, which coordinates the search operations and passes the most relevant information to the language model. The generated response is then streamed back to the website.
The same architecture also supports automatic knowledge-base updates, so changes to website content don't require the chatbot to be manually rebuilt.
Building the Knowledge Base: From Website Content to Searchable Information
A RAG chatbot is only as useful as the information it can retrieve. Simply providing a collection of website pages to a language model isn't enough. The content needs to be extracted, processed and organised so that the system can identify the right information for each question.
Extracting and preparing CMS content
The first step was to retrieve relevant information from the Emkionyx CMS. This included product details, solution pages, company information, services, FAQs and other content that visitors might need help finding.
The extracted content was then prepared for the retrieval pipeline. Instead of treating each page as one large document, I divided it into smaller, self-contained text chunks.
Why chunking matters
Consider a visitor asking about a specific feature of a product. The relevant information might be contained in just a few paragraphs of a much larger page. Retrieving the entire page could introduce unrelated information and take up valuable context space.
Chunking addresses this by dividing documents into smaller sections that can be retrieved independently. Each chunk should retain enough information to make sense on its own, rather than becoming an isolated sentence without context.
This allows the retrieval system to identify specific pieces of information instead of repeatedly returning entire documents.
Converting text into embeddings
Once the content was chunked, each chunk was converted into a vector representation using an embedding model.
An embedding represents the semantic meaning of text numerically. This makes it possible to compare the meaning of a visitor's question with the meaning of the stored content, rather than depending exclusively on exact keyword matches.
For example, a visitor might describe a requirement using different terminology from the website. A semantic search can still identify content that is conceptually related to the question.
The resulting embeddings are stored separately from the original text. Alongside them, I retained the raw chunk content and its associated metadata so that the retrieval system could access the actual information after identifying relevant matches.
This distinction is important: embeddings help locate relevant content, but the language model needs the original text to construct an answer.
Hybrid Retrieval: Finding Information Through Meaning and Keywords
Retrieval is one of the most important parts of a RAG system. The language model can only generate a useful answer if the information supplied to it is relevant to the question.
I didn't want the chatbot to depend exclusively on semantic search. While vector similarity is useful for identifying conceptually related information, exact terminology can be equally important, particularly when visitors ask about specific products, categories or technical terms.
So I implemented a hybrid retrieval approach that combines semantic search with keyword search.
Semantic search
When a visitor submits a question, the backend generates an embedding for it. This query embedding is compared with the stored content embeddings to identify chunks that are semantically similar.
The advantage is that the system doesn't require the visitor to use the exact words found on the website. It can identify related information based on the meaning of the question.
Keyword search
At the same time, a separate full-text search is performed against the stored text.
This is useful when a question includes exact product names, technical terminology or specific phrases. These terms may be important even when the overall semantic similarity score isn't particularly high.
Combining both retrieval methods
The semantic and keyword searches run simultaneously. Their results are then combined into a single ranked list, from which the most relevant chunks are selected.
This approach brings together two complementary retrieval methods. Semantic search helps identify information based on meaning, while keyword search helps identify direct textual matches.
Using both makes the retrieval process more flexible than relying on either method alone.
Using metadata to narrow down product-specific searches
Another consideration was the relevance of the retrieved information.
Suppose a visitor asks about a particular product or category. Searching the entire knowledge base could return content from other products simply because the wording is similar.
To address this, I incorporated metadata filtering into the retrieval process. When a question identifies a specific product or category, the search can be narrowed to the corresponding entity's content.
This prevents unrelated but semantically similar chunks from crowding out the information that is actually relevant to the question.
The retrieved chunks are then passed to the language model as grounding context.
Keeping the Chatbot Focused: The Offline Query Gate
A website chatbot powered by a capable language model can potentially answer questions far beyond the purpose for which it was built. But should it?
I had come across an interesting example involving McDonald's AI assistant and the possibility of users asking it unrelated questions, including coding-related requests. It made me think about how easily a specialised chatbot could end up being used as a general-purpose AI tool.
For Emkionyx, that wasn't the objective.
The chatbot was meant to help visitors understand the company's products, solutions and services. If someone asked it to write a Python script or explain an unrelated programming concept, answering that question would consume model resources without contributing to the chatbot's intended purpose.
I wanted to filter such requests before they reached the more resource-intensive stages of the RAG pipeline.
This led me to introduce an offline query gate.
The incoming question is first checked against the chatbot's intended scope. Requests that fall outside that scope can be rejected before embedding generation, retrieval and language model inference are triggered.
The idea is straightforward: don't spend resources processing a request that the chatbot shouldn't be answering in the first place.
This adds a layer of control over the assistant's behaviour and helps avoid unnecessary model usage. It also reinforces an important consideration when building specialised AI applications: a chatbot doesn't necessarily need to answer everything to be useful.
Generating Responses and Streaming Them to the Website
Once the retrieval system identifies the most relevant chunks, the next step is response generation.
The selected content is passed to the language model as grounding context. The model uses this information to construct a response to the visitor's question.
This is what makes the RAG approach different from sending a question directly to a general-purpose model. The generation process is supported by information retrieved from the Emkionyx knowledge base.
But generating a response is only one part of the experience. I also wanted the answer to appear on the website without making visitors wait for the entire response to finish.
Streaming responses using Server-Sent Events
I used Server-Sent Events (SSE) to stream the model's response back to the browser.
Instead of waiting for the model to generate the complete answer before displaying it, the response is delivered progressively as tokens are generated.
The backend forwards the stream directly to the browser without buffering the entire response. This means visitors can start reading the answer while the remaining content is still being generated.
It makes the interaction feel more immediate and avoids the experience of submitting a question and waiting for a complete block of text to suddenly appear.
Keeping the Knowledge Base Updated Automatically
A chatbot connected to website content also needs a way to stay updated when that content changes.
Imagine a product page being modified in the CMS. If the chatbot continues using the older version of that content, it could provide outdated information even though the website itself has already been updated.
I wanted to avoid manually rebuilding the knowledge base whenever a document changed.
For this, I implemented a webhook-based update mechanism.
When content changes in the CMS, a webhook triggers a backend endpoint that re-fetches the updated document. The document is then processed through the same ingestion pipeline: it is re-chunked, new embeddings are generated, and the updated information is written to the knowledge stores.
This updates both the vector representations used for semantic retrieval and the original text used for keyword search and response generation.
As a result, the knowledge base stays synchronized with the CMS automatically, without requiring a complete rebuild or redeployment every time website content is modified.
Giving the Chatbot a Personality: Introducing Emkioween
The technical side of the chatbot was only one part of the experience. I also wanted its interface to feel like something visitors would recognize rather than another generic chat widget.
This brings us back to Clippy, Merlin and Rover. Those early assistants were memorable not just because of what they did, but because of how they presented themselves. They had a distinct appearance that made them feel like characters rather than ordinary software controls.
I wanted to experiment with that idea.
Before Halloween: The Emkionyx Chatbot

The initial chatbot had a more conventional assistant interface, designed around helping visitors ask questions and explore the company's information.
Its primary purpose was functionality: visitors could interact with it, ask about Emkionyx's offerings and receive responses based on the website's knowledge base.
But Halloween offered an opportunity to do something different.
Introducing Emkioween
For Halloween, I transformed the chatbot into a seasonal mascot called Emkioween.
Instead of the usual assistant appearance, it received a pumpkin head, a witch's hat, a Halloween-themed outfit and a purple glow. The interface was also adapted to match the character.

I didn't want this to be just a visual change. The chatbot also received a small interactive experience built around the familiar Halloween phrase: Trick or Treat?
Trick or Treat?

Visitors were greeted with a Halloween-themed prompt and could choose between Trick and Treat. This gave the assistant a more playful way to interact with website visitors instead of simply displaying the usual chat greeting.
The interesting part was that the transformation happened at the presentation and interaction layer. The underlying RAG system continued to handle knowledge retrieval and response generation. The chatbot could take on a completely different appearance and interaction style without requiring the core knowledge pipeline to be redesigned.
It was a small experiment in making an AI assistant feel more approachable, and one of the more enjoyable parts of the project.
What Goes into Building a Useful Website AI Assistant?
Building the Emkionyx chatbot involved much more than connecting a language model to a website. The project brought together content extraction, chunking, embedding generation, hybrid retrieval, metadata filtering, query control, grounded response generation, streaming and automatic knowledge-base synchronisation.
Each component addressed a different challenge. Retrieval helped the chatbot find relevant information, the offline query gate kept it focused on its intended purpose, streaming improved the interaction, and automated updates kept its knowledge aligned with the website.
But the project wasn't only about the technology. I also wanted the assistant to feel like a recognisable part of the website, rather than just another chat widget.
We started with the idea of making information more accessible through a digital assistant. Along the way, that assistant got its own personality. For Halloween, it became Emkioween, complete with a pumpkin head, a witch's hat and a Trick or Treat interaction.
And that got me thinking: if the chatbot could become Emkioween for Halloween, what could it become next?
Clippy, Merlin and Rover showed us that digital assistants don't always have to be just functional. Sometimes, a little personality makes them memorable. And perhaps this is only the beginning for the Emkionyx assistant. The next transformation might be just around the corner.
Was the blog insightful?
Subscribe to our newsletter so you never miss an update